가상 세포 STATE — 1억6700만 세포로 배운 AI, 신약 실험비 줄일까Virtual cell STATE — can 167 million cell observations help cut research costs?
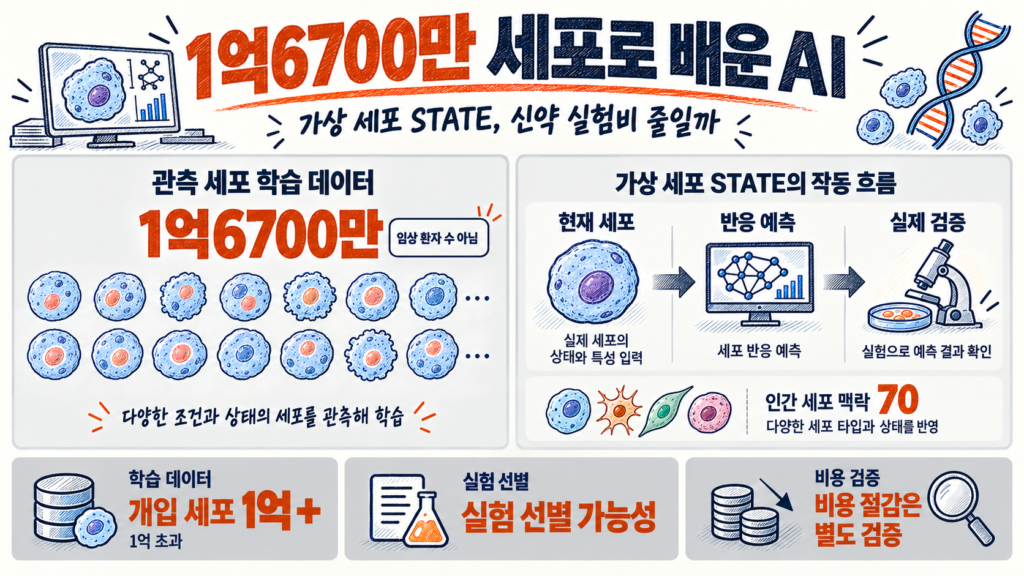
가상 세포 STATE는 약물이나 유전자 변화에 세포가 어떻게 반응할지 예측하는 AI입니다. 세포 상태를 배우는 데 관측 데이터 1억6700만 개가 쓰였습니다. 기대되는 경제적 효과는 유망한 실험을 먼저 고르는 데 있지만, 신약 개발비가 얼마나 줄었는지는 아직 따로 검증해야 합니다. Arc Virtual Cell Initiative
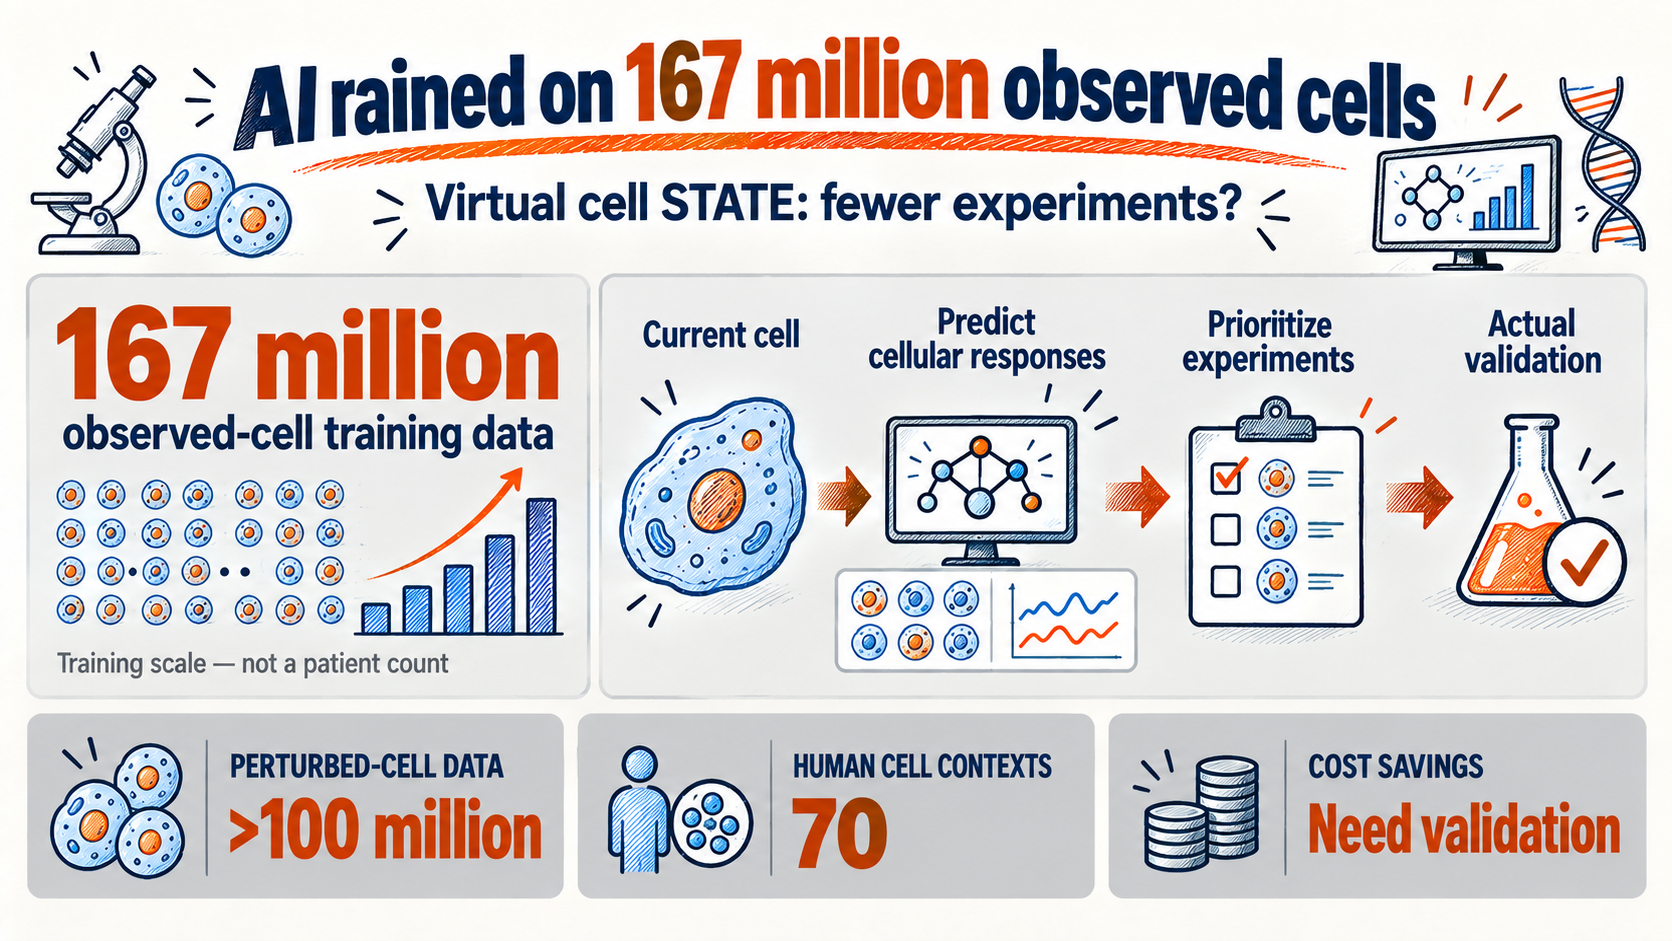
Virtual cell STATE predicts how cells respond to drugs or changes to genes. Its cell-state representation was trained on observations from 167 million cells. The economic opportunity is better experimental prioritization; a reduction in drug-development spending still needs separate evidence. Arc: Virtual Cell Initiative
이 연구는 Cell에 2026년 8월 31일 온라인 공개됐고, 9월 17일자 지면에 실렸습니다. 모델 자체는 2025년에 먼저 공개됐습니다. 이번 소식의 의미는 새로운 이름의 AI가 등장했다는 데 그치지 않습니다. 세포 반응 예측이 실제 연구실의 실험 선택에 얼마나 도움이 되는지 따져볼 근거가 늘었습니다. Cell STATE 논문 서지·초록 (PubMed)
가상 세포 STATE는 무엇을 계산할까
세포 안에서 어떤 유전자가 얼마나 사용되는지는 RNA를 측정해 살펴볼 수 있습니다. RNA는 DNA의 정보를 옮겨 쓰는 분자입니다. 여러 유전자의 RNA 양을 함께 읽으면 세포의 상태를 보여주는 단서를 얻습니다. 이것이 여기서 말하는 유전자 발현 정보입니다. Arc 연구자 인터뷰 (2025-07-13)
기존의 관측 데이터는 세포가 현재 어떤 모습인지를 보여줍니다. 연구자가 정말 알고 싶은 것은 한발 더 나간 질문입니다. 특정 유전자의 작용을 낮추거나 약물을 넣으면 어떤 변화가 생길까요? 이렇게 조건을 의도적으로 바꾸는 실험을 ‘개입’이라고 부르겠습니다. Arc STATE 최초 공개 (2025-06-23)
STATE는 세포 상태를 숫자로 표현하는 부분과, 개입 뒤 변화를 예측하는 부분을 결합합니다. 공식 설명에 따르면 학습에는 1억 개가 넘는 개입 세포 데이터도 쓰였고, 70개 인간 세포 맥락을 다뤘습니다. 세포 맥락은 세포의 종류와 실험 환경 등을 뜻하며, 환자 70명을 의미하지 않습니다. Arc Virtual Cell Initiative
공학적으로 눈여겨볼 점은 세포를 하나씩 고립해서만 보지 않는다는 것입니다. 초기 기술 설명은 세포 집합 안의 관계를 이용해 생물학적 차이와 측정 과정의 차이를 함께 다룬다고 설명합니다. 서로 다른 실험에서 얻은 데이터를 연결하고, 새로운 조건으로 예측을 옮기는 데 필요한 접근입니다. Arc STATE 최초 공개 (2025-06-23)
-
1
현재 세포
RNA 발현 패턴 측정
-
2
개입 조건
약물 또는 유전자 변화 입력
-
3
STATE 예측
개입 후 발현 변화 예상
-
4
실제 검증
예측한 후보를 실험으로 확인
논문 속 성능 개선이 곧 신약 성공률은 아닙니다
논문 초록은 대규모 데이터에서 개입 효과를 구별하는 성능이 비교 기준보다 30% 넘게 개선됐다고 보고합니다. 유전자 발현 변화를 찾는 정확도도 개선됐다고 설명합니다. 이 수치는 논문의 예측 평가 결과입니다. 치료 성공 확률이 30%포인트 올랐거나 연구비가 30% 줄었다는 뜻으로 읽으면 안 됩니다. Cell STATE 논문 서지·초록 (PubMed)
쉽게 말해 RNA 변화 예측과 환자에게 도움이 되는 약을 찾는 일 사이에는 여러 검증 단계가 남아 있습니다. 세포 반응이 그럴듯해도 실제로 원하는 기능이 회복되는지 확인해야 합니다. 이 글에서 경제적 가능성을 후보 실험의 선별 단계에 한정하는 이유입니다.
한계는 새 평가 방식에도 드러납니다. Arc의 2026년 대회는 개입 후 반응을 본 적 없는 세포주 6개를 대상으로 합니다. 기본 상태와 바꿀 유전자만 제공하고 결과를 예측하게 합니다. 익숙한 데이터에서 좋은 점수를 받는 것과 낯선 세포에서 쓸모 있는 예측을 하는 것은 다른 시험입니다. Arc Virtual Cell Challenge 2026 (2026-08-20)
실험비는 어느 지점에서 줄어들까
아래 비용 분석은 논문 실측 결과가 아니라 사업화될 경우의 추론입니다. 먼저 달라질 수 있는 것은 실험 순서입니다. 검토할 조건이 많을 때 유망한 조건부터 시험하면, 같은 인원과 장비로 더 많은 가설을 살펴볼 여지가 생깁니다.
여기서 비용을 줄이는 것은 계산 속도 그 자체보다 생략해도 되는 실험입니다. 시약과 외부 분석 의뢰비처럼 횟수에 따라 발생하는 지출을 줄이면 현금 절감으로 이어질 수 있습니다. 반면 이미 설치한 장비와 상근 인력의 비용은 실험 몇 건을 줄였다고 바로 사라지지 않습니다. 그 경우 먼저 나타나는 효과는 남는 시간과 추가 처리 능력입니다.
계산을 위해 가정을 하나 놓아보겠습니다. 실험 1,000건의 회피 가능한 비용이 건당 10만 원이면 합계는 1억 원입니다. AI로 400건을 골라 시험하고, 데이터 정리·계산·추가 검증에 3,000만 원을 쓴다고 가정하면 총비용은 7,000만 원입니다. 차이는 3,000만 원입니다. 이 숫자는 이해를 위한 가정이며 STATE의 절감 실적이 아닙니다.
기존 방식 가정
1,000건 × 10만 원
실험
회피 가능한 비용 · 1억 원
AI 선별 가정
400건 × 10만 원 = 4,000만 원
실험
데이터·계산·추가 검증 · 3,000만 원
합계 / 차액 · 7,000만 원 / 3,000만 원
이 계산에는 강한 전제가 숨어 있습니다. 400건만 시험해도 유효한 후보를 찾는 성과가 유지돼야 합니다. AI가 좋은 후보를 탈락시키면 당장 절약한 실험비보다 잃는 기회가 클 수 있습니다. 따라서 기업이 확인할 숫자는 생략한 실험 건수와 함께, 실제 검증에서 찾아낸 유효 후보 수입니다.
결국 줄인 실험비가 AI를 도입하고 검증하는 데 든 돈보다 커야 합니다.
여기에는 데이터 확보비와 계산비, 도입비, 추가 검증비를 모두 넣어야 합니다. 예측이 자주 틀려 재실험이 늘어나면 절감 효과는 사라집니다. 그래서 학습 데이터와 가까운 좁은 용도에서 먼저 가치를 입증하는 편이 사업적으로 합리적이라고 봅니다.
3,000만 달러는 모델보다 데이터에 먼저 들어갔습니다
이 분야의 산업적 움직임을 보여주는 사례가 Tahoe Therapeutics입니다. 회사는 2025년 8월 11일 데이터 구축을 위한 신규 투자 3,000만 달러를 발표했습니다. 당시 제시한 10억 세포 데이터와 100만 약물–환자 상호작용은 구축 계획입니다. 2026년에 목표를 달성했다는 의미로 옮겨 쓰지는 않겠습니다. Tahoe 투자 유치 발표 (2025-08-11)
투자 유치는 고객 매출이나 기술의 수익성을 증명하지 않습니다. 다만 자본이 어디에 투입되는지 보여줍니다. 이 사례에서 돈의 사용처는 AI 학습에 필요한 실제 반응 데이터를 만드는 일입니다. 공개 관측 데이터를 많이 모으는 것과, 특정 약물이 특정 세포를 어떻게 바꾸는지 측정하는 것은 별도의 생산 활동입니다.
Myllia도 STATE의 학습과 검증에 단일세포 CRISPR 스크리닝 데이터를 제공했다고 밝혔습니다. CRISPR 스크리닝은 여러 유전자의 작용을 바꿔 보며 그 영향을 조사하는 실험입니다. 회사 발표라는 점을 전제로 보면, 모델 개발 조직과 실험 데이터를 생산하는 조직이 역할을 나누는 사례입니다. Myllia STATE 공동연구 공식 발표
제 판단으로는 질환과 관련된 세포를 확보하고, 같은 품질로 반복 측정하며, 데이터의 이용 권한까지 제공할 수 있는 기업에 새로운 거래 기회가 생길 수 있습니다. 고객은 데이터 파일의 크기보다 자기 연구에서 예측이 얼마나 좋아지는지에 돈을 지불할 것입니다. 특수 데이터 공급, 모델 평가, 연구실 시스템 연결 서비스가 가능한 사업 영역입니다.
실험 대행사를 대체할까, 새로운 일을 만들까
산업 대체는 부분적으로 일어날 가능성을 생각할 수 있습니다. 예측으로 걸러낼 수 있는 반복 탐색 실험은 주문이 줄어들 수 있습니다. 반대로 모델이 아직 약한 세포와 질환의 데이터를 만드는 일, 후보를 실제로 검증하는 일은 중요해질 수 있습니다. 이는 전망이며 현재 매출 변화가 확인됐다는 주장은 아닙니다.
국내 연구 서비스 기업에도 적용할 수 있는 질문입니다. 단순히 많은 실험을 빨리 해주는 사업인지, 고객의 특정 질환 연구에 필요한 데이터를 독점적으로 제공할 수 있는 사업인지에 따라 경쟁력이 달라질 수 있습니다. 제약사는 외부 모델을 도입하더라도 자사 데이터 정리와 결과 재현 능력을 확보해야 합니다.
장비와 계산 인프라의 이해관계도 연결돼 있습니다. 2026년 대회에는 NVIDIA, 10x Genomics, Ultima Genomics가 참여합니다. 대회 안내에는 실제 데이터 생성에 10x Flex와 Ultima UG100을 사용했다고 명시돼 있습니다. 이것은 기술 생태계 참여의 증거이며, 해당 기업의 매출 증가율을 계산할 근거는 아닙니다. Arc Virtual Cell Challenge 2026 (2026-08-20)
재현 가능한 성과가 다음 시험대
가상 세포 STATE가 던지는 과학적 질문은 분명합니다. 이미 관측한 세포에서 배운 내용을 다른 세포의 반응 예측으로 옮길 수 있을까요? 산업적 질문은 그 예측 덕분에 같은 예산으로 더 좋은 후보를 찾을 수 있느냐입니다. 두 질문의 답은 각각 검증해야 합니다.
후속 연구에서는 낯선 조건에서도 예측이 맞는지부터 확인해야 합니다. 그다음은 실제 실험으로 확인한 유효 후보가 늘었는지, 데이터와 재검증까지 포함해 비용이 줄었는지입니다. 과학적 성능과 연구실의 생산성을 함께 볼 수 있는 기준입니다.
모델의 점수 하나만으로는 이 질문들에 답할 수 없습니다.
연구팀은 STATE 코드와 관련 도구를 공개하고 있습니다. 기업이 이를 제품이나 유료 서비스에 연결할 때는 코드·모델·데이터 각각의 이용 조건도 확인해야 합니다. 공개돼 있다는 사실과 모든 상업적 용도가 허용된다는 것은 같은 말이 아닙니다. STATE 공식 코드 저장소
지금 기대할 만한 변화는 연구자가 더 많은 후보를 검토하고, 실제 실험은 더 신중하게 선택하는 방식입니다. 그 과정이 검증되면 연구비의 일부가 반복 실험에서 양질의 데이터와 예측 검증으로 이동할 수 있습니다. 이 글은 2026년 9월 23일까지 확인한 자료를 바탕으로 한 기술·산업 분석이며, 특정 기업에 대한 투자 권유는 아닙니다.
예측의 가치는 실제 실험으로 확인한 유효 후보와 그 후보를 찾는 데 든 비용으로 판단해야 합니다.
출처와 참고 링크
The study appeared online in Cell on August 31, 2026, and in its September 17 issue. STATE itself was first released in 2025. The new publication adds evidence for evaluating an existing approach, rather than marking the invention of virtual cells. Cell paper abstract and publication record
What does virtual cell STATE actually predict?
RNA carries information transcribed from DNA. Measuring RNA across many genes gives researchers clues about a cell’s current state. This pattern is called gene expression. It is a useful biological readout, rather than a complete description of everything happening inside a cell. Arc: researcher interview
Observational data describe cells as they are. Researchers also want to know what will happen after a deliberate intervention, such as reducing a gene’s activity or adding a drug. Measurements before and after an intervention provide a different kind of evidence from observations alone. Arc: original STATE announcement, 2025
STATE combines a representation of cell state with a module that predicts transitions after intervention. Arc reports using more than 100 million perturbed-cell observations across 70 human cell contexts. A context refers to a cellular or experimental setting, not an individual patient. Arc: Virtual Cell Initiative
An engineering feature is the use of relationships across sets of cells. The original technical announcement describes this as a way to accommodate biological variation and differences introduced by measurements. Such variation matters when combining experiments and transferring predictions to another setting. Arc: original STATE announcement, 2025
-
1
Starting cells
Measure RNA expression
-
2
Intervention
Specify drug or genetic change
-
3
STATE prediction
Predict expression response
-
4
Physical validation
Test selected candidates
An improved prediction metric is not a drug-success rate
The abstract reports more than a 30% improvement in discriminating perturbation effects on large datasets, alongside better identification of changes in gene expression. This is a prediction result. It does not establish a 30-percentage-point increase in treatment success or a 30% reduction in research costs. Cell paper abstract and publication record
Predicting an RNA response and finding a medicine that benefits patients are different endpoints. Researchers still need to test whether the desired biological function changes. The economic analysis here therefore concerns prioritizing early experiments, rather than replacing downstream validation.
Arc’s 2026 challenge tests six cell lines whose perturbation responses are withheld. Participants receive their baseline states and the genes to target. This tests transfer into unfamiliar cellular settings, a harder and more practically relevant task than prediction among familiar examples. Arc: 2026 Virtual Cell Challenge
Where could experimental spending fall?
The following cost analysis is a commercialization scenario, not a measured result from the paper. The first change could be the order of experiments. Testing promising conditions first could let a team examine more hypotheses with the same people and equipment.
The cash benefit comes from experiments that can safely be omitted. Reagents and outsourced analyses may be avoidable costs. Installed equipment and permanent staff generally remain, so fewer assays may initially create spare capacity rather than an equivalent reduction in spending.
Consider an illustrative calculation. At KRW 100,000 of avoidable cost per test, 1,000 tests cost KRW 100 million. Suppose a model selects 400 tests, while data preparation, computation and extra validation cost KRW 30 million. Total spending becomes KRW 70 million, leaving KRW 30 million in savings. None of these assumptions is a measured STATE result.
Illustrative baseline
1,000 × KRW 100,000
Tests
Avoidable spending · KRW 100 million
Illustrative AI selection
400 × KRW 100,000 = KRW 40m
Tests
Data, compute, extra validation · KRW 30 million
Total / savings · KRW 70 million / KRW 30 million
The crucial assumption is that testing only 400 conditions preserves useful discoveries. Rejecting a valuable candidate could cost more than the assays saved. A business evaluation should therefore track both omitted experiments and experimentally validated hits.
The experiments saved must cost more than introducing and validating the AI.
That calculation must include data acquisition, computation, deployment and extra validation. Repeated experiments after failed predictions can erase the benefit. My inference is that a narrow application with relevant training data offers a more credible initial business case.
A $30 million funding announcement puts data in focus
Tahoe Therapeutics announced $30 million in new funding on August 11, 2025, for building data for virtual cell models. Its billion-cell and million drug–patient interaction figures were announced targets. They should not be treated as verified 2026 delivery milestones. Tahoe: funding announcement, 2025
Funding is not proof of customer revenue or profitability. It does reveal an intended use of capital: generating experimental responses for model training. Collecting existing observations and producing new intervention measurements are distinct activities. This distinction matters when asking who might earn revenue.
Myllia states that it supplied single-cell CRISPR screening data for STATE training and validation. Such screening changes gene activity and measures the effects. This company announcement illustrates a division of work between model builders and experimental data producers; it does not establish a particular revenue outcome. Myllia: research contribution
My inference is that opportunities could emerge for suppliers offering disease-relevant cells, reproducible measurements and usable data rights. Buyers would ultimately pay for better decisions in their own research, rather than file size. Specialized datasets, model evaluation and laboratory integration are plausible service markets.
Would this replace experimental services or create more work?
Partial substitution is plausible. Routine exploratory assays might face lower demand if reliable predictions screen them out. Generating data for poorly represented cells and validating candidates could become more valuable. These are prospective effects, not verified changes in industry revenue.
The same question applies to Korean research-service businesses: are they selling assay volume, or hard-to-reproduce evidence for a specific disease program? Drug companies adopting outside models would still need organized internal data and the ability to reproduce results.
Infrastructure suppliers are involved too. NVIDIA, 10x Genomics and Ultima Genomics participate in the 2026 challenge, whose announcement identifies 10x Flex and Ultima UG100 in data generation. This demonstrates ecosystem involvement, not a basis for estimating supplier revenue growth. Arc: 2026 Virtual Cell Challenge
Reproducible results are the next test
STATE raises a scientific question: can information learned from observed cells transfer to responses in another context? The business question is whether those predictions help discover better candidates for the same budget. Each requires its own evidence.
Follow-up studies should first test predictions in unfamiliar conditions. They should then measure validated discoveries and costs that include data preparation and repeat validation. Together, these measures connect scientific performance with laboratory productivity.
A model score alone cannot answer these questions.
The team publishes STATE code and supporting tools. Organizations considering commercial products or paid services should check the applicable terms for code, models and datasets separately. Public availability alone does not settle every commercial-use question. Official STATE repository
The credible near-term opportunity is to consider more candidates and choose physical experiments more carefully. If validated, that could redirect part of research budgets toward better data and prediction testing. This technology and industry analysis uses information checked through September 23, 2026; it is not an investment recommendation.
Judge predictions by validated discoveries and the cost of finding them.
Sources and further reading
이 글은 정보 제공 목적이며, 특정 자산의 매수·매도를 권유하지 않습니다.
For information only — this is not a recommendation to buy or sell any asset.
댓글Comments 0